Modulate Earns #1 Spot on Hugging Face's Transcription Benchmark

 Australia's High Court rules against coal mine in landmark climate case
 Australia touts new funds for Pacific infrastructure at Fiji 'pre-COP'
 Eva Marie Saint, Oscar winner of Hollywood classics, dies at 102
 Australia probes app used in cheap smart glasses over privacy fears
 England needed to 'move on' from World Cup pain, says Tuchel
 O'Neill to stay at Celtic after period of "reflection"
 Kane marks 125th England cap with Wembley Nations League double
 Quebec's incoming separatist leader wants to block Crown from swearing-in
 Emmys gala will now stream its premier television awards
 Paramount completes Warner Bros takeover, creating Skydance
 Trump blames France unrest on Islam, migration
 Apple's Cook praises EU over efforts to protect children online
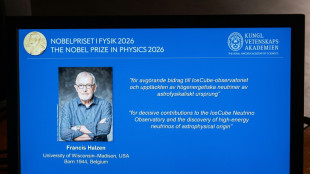 Nobel winner Halzen says years of October 'misery' finally over
 Quebec separatist win rattles Carney's unity push
 'Itching' for change: Shiffrin cuts back slaloms this season
 'Gen Z has risen up': Tens of thousands mass for tense France school protests
 Caribbean tourism hotspot loses men to Russian war machine
 Danish reservists practice war games to respond to 'aggression'
 Bhuvneshwar returns to India's T20 squad for New Zealand tour
 Asos says probing 'unauthorised activity' after phone alerts
 Stocks climb as oil prices retreat under $100 per barrel
 Neutrinos: space particles that change our view of universe
 'Destined' Djokovic wins China Open, extending unbeaten record
 Iceland is 'critical outpost' for security, says Rubio during visit
 Israeli settlers beat AFP photographer covering West Bank
Modulate's enterprise transcription API combines leading speech recognition accuracy, production-ready streaming performance, and pricing up to 10x lower than other major transcription API providers. Independent rankings validate its performance among the industry's leading commercial speech-to-text models.
BOSTON, MA / ACCESS Newswire / July 13, 2026 / Modulate, the frontier conversational voice intelligence company, now ranks #1 on Hugging Face's Open ASR Leaderboard, one of the industry's most widely followed public benchmarks for automatic speech recognition, also known as speech-to-text. The achievements signify Modulate's momentum in delivering the industry's fastest, most accurate, and most cost-efficient speech-to-text model for real-world voice applications.

The milestone underscores how Modulate's unique voice-native architecture can outperform much larger players across the metrics that matter most to enterprises: accuracy, speed, and cost. The ranking demonstrates that specialized AI models purpose-built for conversational audio can compete at the highest levels without relying on increasingly large and expensive foundation models.
"Transcription has become foundational to voice AI, but the economics have not kept up with how these systems are actually being deployed," said Mike Pappas, CEO and co-founder of Modulate. "Developers and enterprises should not have to choose between accuracy, speed, and affordability. Modulate delivers all three, while opening the door to a much deeper understanding of what is happening in live conversations."
The Hugging Face Open ASR Leaderboard provides a transparent, reproducible comparison of leading open-source and commercial transcription models across standardized datasets spanning multiple domains, accents, and recording conditions. Models are evaluated using Word Error Rate, or WER, the standard metric for transcription accuracy that measures the percentage of words a model gets wrong, with a lower WER indicating higher accuracy. Modulate ranked #1 out of 88 models, demonstrating Modulate's ability to deliver state-of-the-art transcription accuracy at the most competitive price point available.
As transcription becomes critical infrastructure for voice agents, contact centers, fraud detection, customer experience, and conversational AI workflows, enterprises and developers are increasingly demanding solutions that can perform at scale. Modulate meets that need, delivering high-performance transcription while serving as an entry point into Modulate's broader Velma platform for voice-native conversation understanding.
More Than a Technical Scorecard
For developers evaluating transcription models, independent validation on benchmark performance gives confidence that models will perform as expected in real-world conditions. In large-scale environments, even small differences in transcription accuracy and price can translate into meaningful differences in reliability, customer experience, and operating cost.
Modulate trains its models on more than 500 million hours of noisy, real-world audio, giving it a strong foundation for environments where speech is not clean, scripted, or studio-quality. The model transcribes faster than real time, which is essential for live transcription, streaming applications, and other voice workflows where latency directly affects user experience.
Unlike conventional transcription tools that focus primarily on converting speech to text, Transcription is part of Modulate's broader voice intelligence platform, built to understand real-world audio signals that transcripts alone cannot capture. Modulate's Ensemble Listening Model, or ELM, architecture combines dozens of audio-native models designed to understand voice, enabling Modulate to deliver highly accurate, production-ready audio intelligence at a fraction of the cost of larger, more generalized models or LLM-first approaches.
Advanced Voice Intelligence That Goes Beyond Flattened Text
In addition to high-accuracy transcription, Modulate's transcription models support advanced voice intelligence capabilities including emotion detection derived from audio signals rather than transcript text, diarization, accent identification, deepfake detection, and support for 57+ languages and dialects.
These capabilities are especially important as voice AI moves from controlled demos into live, high-stakes environments. In contact centers, AI agents, fraud prevention workflows, and enterprise voice applications, what matters is not only what was said, but how it was said, who said it, whether the voice can be trusted, and what context is emerging in the conversation.
"Transcription is an important starting point, but it is not the end state," said Pappas. "The real opportunity is conversation understanding. Voice carries signals like emotion, urgency, hesitation, accent, identity, and authenticity that never appear in a transcript. Velma is built to help enterprises capture those signals and turn them into actionable intelligence."
Most voice pipelines still begin by flattening audio into text, then passing that text into an LLM or other downstream system. While that approach has become standard, it discards much of the meaning contained in the original audio, including tone, intent, speaker dynamics, interruptions, sarcasm, emotion, and other conversational signals that can change how a conversation should be understood.
Velma combines Modulate's industry-leading transcription models with these additional acoustic signals, enabling a richer understanding of conversations which powers content moderation, fraud prevention, customer experience, and trust and safety use cases. Modulate's approach is grounded in real-world audio, including noisy, high-scale, emotionally complex voice environments where accuracy, latency, cost, and explainability are essential to production deployment.
Modulate by the Hugging Face Numbers
Modulate's transcription offerings are available at prices between $0.025 and $0.06 per hour, compared with $0.22-0.39 per hour for ElevenLabs Scribe v2, $0.21-0.45 per hour for AssemblyAI Universal 3 Pro, and $0.31-0.55 per hour for Deepgram Nova-3, making Modulate 7x to 10x less expensive than several other leading transcription API providers, while delivering the highest accuracy on Hugging Face's ASR benchmark.
Hugging Face's Open ASR Leaderboard evaluates models across seven datasets, including AMI, Earnings-22, GigaSpeech, LibriSpeech Clean, LibriSpeech Other, SPGI Speech, and VoxPopuli-AA-Cleaned. AMI, which consists of noisy real-world meeting audio, is widely regarded as one of the most difficult datasets, as it reflects the kind of messy, multi-speaker environments where enterprise transcription models must actually perform.
These transcription models, as well as other unique models for emotion understanding, behavior analysis, and much more, are all available today through Modulate's API. To learn more, visit https://www.modulate.ai/.
About Modulate
Modulate is a voice intelligence company building AI models and APIs designed to understand real-world conversational audio at scale. Its technology combines speech recognition, acoustic analysis, and conversational context to deliver reliable, explainable, and cost-effective voice intelligence for developers and enterprises.
For more information or to get started, visit modulate.ai.
Media Contact
Kristin Canders
Grithaus Agency
(e) [email protected]
###
SOURCE: Modulate
View the original press release on ACCESS Newswire
P.Hernandez--AT